Semi-Supervised Learning: Combining Labeled and Unlabeled Data for Model Training in Resource-Constrained Scenarios
Introduction
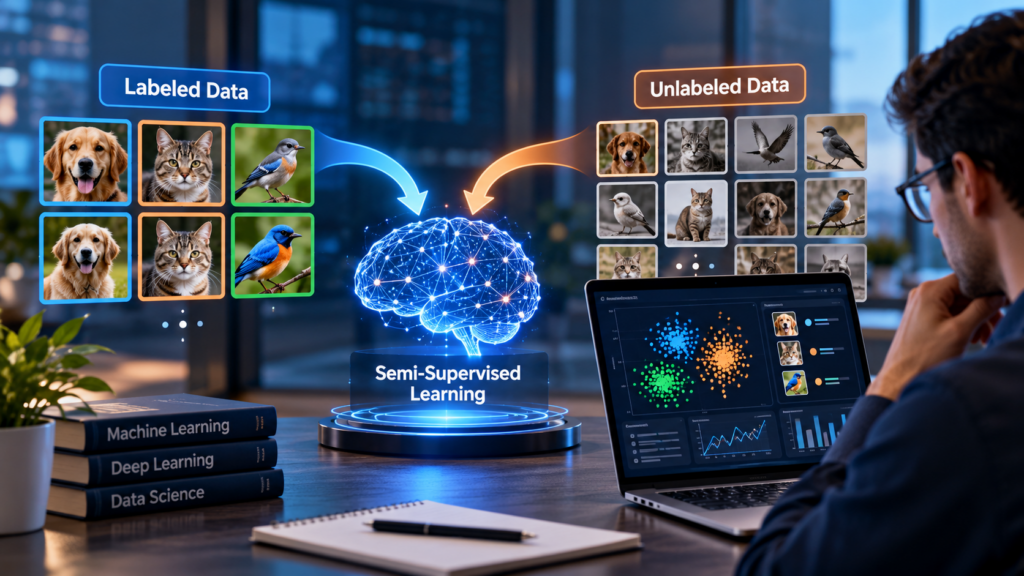
Labeled data is the lifeblood of supervised machine learning and like most forms of currency it’s very expensive to get. A radiologist going through scans to label the presence of tumours, a lawyer going through documents to label them as contracts, a linguist going through audio to label the dialects present etc etc: all of these annotation tasks cost time, expertise and money. The raw data itself on the other hand is often in huge quantities. Semi-supervised learning is the approach that directly deals with this imbalance. It’s a class of ML techniques that will train a model using a small amount of labeled data and a very large amount of unlabeled data. The result is a model that is typically much more capable than one trained on labeled data alone. Knowing when and how this works is an area of practical importance in any serious data analytics course that deals with real world data constraints.
The Fundamental Asymmetry: Why Labeled Data Is Scarce
In the vast majority of supervised learning pipelines the assumption is that you have a sufficiently large labelled dataset. In reality this assumption fails across the board in most industries. Medical imaging is the most obvious case in point: you certainly have a dataset of 100,000 chest X-rays that is of clinical value. The problem is that having a clinician go through and label each of those 100,000 images in terms of pathology type, severity and location would take years and would cost millions of pounds. The unlabelled images are there, the labels are not.
This is not a minor issue. A McKinsey Global Institute 2020 survey identified data labelling as one of the top three impediments to enterprise AI deployment, with annotation costs representing 20-35% of the total ML project spend in most sectors. Semi-supervised learning doesn’t remove the labelling bottleneck entirely, it just dramatically mitigates it by leveraging the structure present in the unlabelled data to improve the model’s generalisation.
The fundamental assumption that underpins this is the smoothness assumption: points that are close together in feature space are likely to have the same label. If a model can learn the geometry of the data from the unlabeled examples (i.e. it can learn what the clusters are, where the density is, where the natural boundaries are) then it can use that to make better decisions in regions where there are no labels.
Core Techniques: How Semi-Supervised Learning Works in Practice
Several quite different methodological approaches fall into the semi-supervised category, each in its own way making use of the unlabeled data.
Self training is the simplest approach. You train the model on the available labelled data. You then apply the model to the unlabelled data and take the predictions it makes with the highest confidence and add those as pseudo labels to the training set. The model is then retrained on the expanded dataset and the process is repeated. It’s computationally very straightforward but there’s a danger of perpetuating early errors if the model is not well calibrated in the first place. Wrong predictions made with high confidence will be added to the training data and so will propagate through the subsequent training cycles. That’s why confidence thresholds and iterative validation are such important elements in any self training pipeline.
Label Propagation is a graph based approach. Each data point (both labelled and unlabelled) is a node in the graph, with edges between nodes weighted by the similarity of the points. The labels from the labelled data points “spread” through the graph to the unlabelled nodes, propagating iteratively until all the nodes have a predicted label. It’s a method which explicitly takes into account the geometry of the data and can work very well when the labelled and unlabelled data are drawn from the same underlying distribution.
Co-training is the case when your data can be described by two separate views. You train a model on each view separately using labelled data and then have each model label the examples in the other view. Blum and Mitchell’s original 1998 paper on this is a classic, using web page classification as the example. The text of the page and the anchor text of the links were the two views. Neither view by itself was good enough, but together they produced a very good classifier with very little labelling.
Consistency Regularisation (the backbone of many modern semi-supervised methods) is really quite simple in principle: a model should give the same output for a given data point irrespective of small perturbations to that data point. During training you augment your unlabeled data (rotate it, crop it, add noise etc) and penalise the model if its prediction on the original and the augmented version are different. This is the principle behind MixMatch and FixMatch amongst others and has proven to be a very effective approach on image classification benchmarks. In the 2020 FixMatch paper from Google Research they achieved 94.93% accuracy on CIFAR-10 using just 40 labelled examples. That would have been absolutely impossible with supervised learning on that small a number of labels.
For the learner in a data analyst course in Vizag encountering semi-supervised methods for the first time, self-training and label propagation are the obvious first steps. They’re the most mechanically transparent and they map directly onto the concepts of supervised classification and graph theory that the majority of intermediate learners will already be familiar with.
Real-World Applications Across Resource-Constrained Domains
The practical value of semi-supervised learning is most apparent in domains where annotation is either expensive, time-consuming or requires specialist knowledge.
Healthcare Imaging: Stanford’s CheXNet project (which classifies 14 thoracic pathologies from chest X-rays) made use of semi-supervised techniques to augment its labelled training data with unlabelled clinical images. The model achieved at or above radiologist level on pneumonia detection and this result was specifically attributed to the need for the structural information in the unlabelled data.
Natural Language Processing: Large language models (BERT, GPT etc) are trained in a self-supervised manner (a form of semi-supervised learning) on huge volumes of unlabelled text. They are then fine-tuned on small amounts of labelled data for a particular task. BERT, for instance, was pre-trained on unlabelled text from Wikipedia and BookCorpus and when fine-tuned on a very small amount of labelled data achieved state-of-the-art results on 11 NLP benchmarks. The pre-training and fine-tuning approach is now the dominant paradigm in applied NLP and is effectively semi-supervised learning at scale.
Industrial Quality Control: manufacturing lines produce tens of thousands of images per hour. Defects may be as low as 1% of the output so the number of labelled defect examples is extremely limited. Semi-supervised methods have been used in the automotive and semiconductor industries where they are trained on the huge number of images of normal product (the unlabeled data) plus a small number of labelled defect examples. The result is defect detection rates in excess of 95% which is equivalent to the performance of a fully supervised model trained on a dataset 10x larger.
Satellite imagery analysis (the annotation of land cover types such as forests and urban areas and agricultural land) is something that requires domain expertise and is utterly impractical at a continental scale. Semi-supervised label propagation applied to partially labelled satellite datasets has enabled environmental monitoring systems to classify land cover globally with labelling effort reduced by an estimated 70% (esa 2021 Earth Observation programme).
This is precisely why semi-supervised learning is starting to appear more and more in the advanced data analytics course material — it’s not some esoteric technique, it’s a practical approach that applies to the vast majority of real world situations where you have a limited amount of labelled data and a massive amount of unlabelled data.
When Semi-Supervised Learning Works — and When It Does Not
Semi-supervised learning isn’t a panacea. It only works if the smoothness assumption is valid i.e. if the structure that you can see in the unlabeled data is actually the structure that would be present in the labelling. If the smoothness assumption is broken (i.e. if the class boundaries are cutting through the dense regions of the feature space rather than the sparse regions) then the unlabeled data can actually mislead the model rather than help it.
Three conditions will lead to an effective semi-supervised application: the labelled and unlabelled data are from the same distribution; the class boundaries lie in regions of low data density; and the unlabelled dataset is vastly larger than the labelled dataset. Under these circumstances semi-supervised methods will beat the supervised baselines trained on the labelled data alone.
When they don’t hold (particularly in the case of a distribution shift between the labelled and the unlabelled data) semi-supervised methods can in fact end up performing worse. This is a well-documented failure mode which must be tested for explicitly by the analyst (usually by watching the performance of the model on held out labelled data over the course of training).
For the data analyst course participants in Vizag applying these techniques to domain specific data, the practical discipline of checking that the smoothness assumption holds prior to even considering a semi-supervised pipeline is just as important as knowing the algorithms.
Concluding Note
Semi-supervised learning sits in a very practical middle ground between the data deluge that you need for supervised learning and the total lack of labels that unsupervised learning is designed to cope with. It works by extracting the geometric and structural information from the unlabeled data which in turn enables the model to generalise much better when you’re constrained by a limited annotation budget. That’s the reality for most machine learning projects in the real world. You’ll find semi-supervised learning going from the research stage into production systems across a wide variety of domains (medical imaging, industrial inspection, large scale NLP etc) with real and demonstrable impact.
The techniques themselves (self training, label propagation, co-training, consistency regularisation) are very different in their mechanism but all operate on the same principle: unlabeled data can contain information that is useful to learn from. For anyone going through a data analytics course with an eye on applied ML, semi-supervised learning is absolutely a must know area. It’s the area that deals with the reality of the situation in that we’re all going to be working with data that is not fully labelled. The classroom assumption is that you have full labels, in reality you don’t.
Contact Us:
Name: ExcelR- Data Science, Data Analyst, Business Analyst Course Training in Kolkata
Address:19/1 Camac Street B. Ghose Building, 2nd Floor, opposite Fort Knox, Kolkata, West Bengal 700017
Phone No.: 8591364838
Email ID: enquiry@excelr.com