Composite Keys Logic: Using Multiple Columns to Uniquely Identify a Specific Record
In relational database design, one of the most fundamental requirements is the ability to uniquely identify every record in a table. A single column is often sufficient for this purpose — an auto-generated customer ID or a product code, for instance, serves as a clean, unambiguous identifier. But there are many real-world situations where no single column can guarantee uniqueness on its own, and where the combination of two or more columns is what makes a record distinct. This is the logic behind composite keys — a foundational concept in database design that has practical implications for data integrity, query performance, and analytical accuracy across virtually every industry that relies on structured data.
What a Composite Key Is and Why Single Keys Are Sometimes Insufficient
A composite key, also called a compound key, is a primary key that consists of two or more columns working together to uniquely identify a row in a database table. Neither column alone is sufficient to distinguish one record from another, but their combination is.
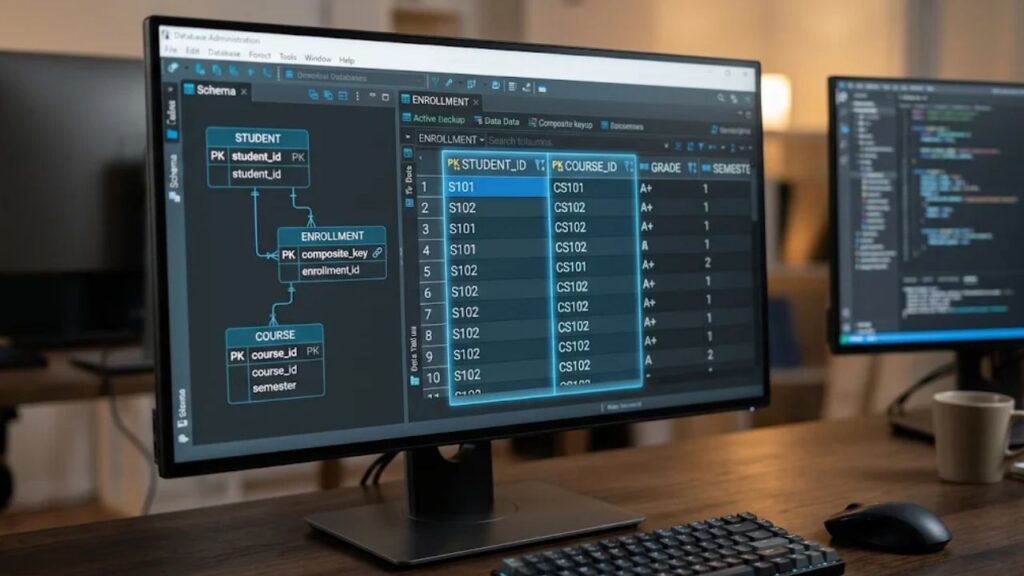
To understand why this becomes necessary, consider a university’s course enrollment database. A student with ID 1042 may be enrolled in multiple courses, and a course with ID ENG201 may have many students enrolled in it. Neither the student ID nor the course ID alone can uniquely identify a specific enrollment record — the same student ID appears multiple times (once per course), and the same course ID appears multiple times (once per student). The combination of student ID and course ID, however, identifies a single, unique enrollment event. That pairing is a composite key.
This scenario is not unusual. It arises consistently in tables that represent relationships between entities — enrollment records, order line items, employee project assignments, seat reservations, or any other junction between two entities where multiple records can share the same value in either column individually. In database design terminology, these are called junction tables or associative entities, and composite keys are their natural identifier structure.
The alternative — assigning an arbitrary auto-generated ID to each row and treating that as the primary key — is a legitimate approach, but it does not enforce uniqueness at the data level. Without a composite key constraint, a database would accept duplicate enrollment records for the same student-course combination, potentially creating data integrity problems that are difficult to detect and costly to correct after the fact. A composite key prevents this by telling the database system to reject any insert or update that would produce a duplicate combination.
How Composite Keys Function in Practice
At the implementation level, a composite key is declared during table creation by specifying multiple columns in the PRIMARY KEY constraint. In SQL, this looks like defining both columns together within the constraint definition rather than attaching the key designation to a single column. Once defined, the database engine enforces uniqueness across that combination automatically — any attempt to insert a row with a student-course pairing that already exists in the enrollment table will be rejected with a constraint violation error.
Composite keys also function as foreign keys in related tables. When one table needs to reference a record identified by a composite key in another table, it must include all the columns that make up that composite key. This maintains referential integrity — the guarantee that every reference in the database points to a real, existing record — across the full identifier, not just a partial match.
Query behavior changes meaningfully when composite keys are involved. A SELECT or JOIN operation on a table with a composite primary key must use all components of that key to retrieve or link records precisely. An analyst querying enrollment data to find a specific student’s record in a specific course must filter by both student ID and course ID; filtering by student ID alone returns all of that student’s enrollments, and filtering by course ID alone returns all enrollments for that course.
Index performance is another practical consideration. Composite primary keys create composite indexes — indexes built on the combination of columns rather than any individual column. The order in which columns are declared in the composite key affects index efficiency. Columns that are queried or filtered most frequently should appear first in the key declaration to optimize index usage during common query patterns. This is a nuance that matters in high-volume production databases where query performance is measured in milliseconds.
These implementation details are covered systematically in structured SQL and database design curricula. A well-rounded Data Analytics Course will address composite keys not just as a definitional concept but as a practical design tool, with exercises that involve creating and querying tables that use multi-column identifiers in realistic scenarios.
Real-World Applications Across Industries
Composite keys appear in the data architecture of nearly every sector that manages relational data at scale, and examining where they appear helps clarify why their logic is important beyond academic database design.
In e-commerce and retail, order management systems use composite keys to structure order line item tables. A single order may contain multiple products, and each product may appear across thousands of orders. The combination of order ID and product ID forms the composite key for the line item table — uniquely identifying which product was purchased as part of which order, at what quantity and price. Attempting to use either column alone as a primary key would be structurally invalid given that both repeat extensively across the table.
In healthcare, appointment scheduling systems use composite keys to manage patient-provider relationships across time. A patient may see the same provider multiple times, and a provider may see the same patient multiple times. The combination of patient ID, provider ID, and appointment date and time creates a unique identifier for each appointment record. Some implementations add a location or facility identifier as well, forming a composite key across four columns to accommodate multi-site healthcare networks where the same provider operates across different facilities on the same day.
In financial services, trading platforms use composite keys in position tracking tables where a portfolio ID and security ID together identify a holding. Since the same security can be held across multiple portfolios and the same portfolio holds multiple securities, neither column individually serves as a unique identifier. The composite key ensures that each portfolio-security combination maps to exactly one position record — preventing double-counting in portfolio valuation reports, which would have serious downstream consequences for risk reporting and regulatory compliance.
In logistics and supply chain, shipment tracking systems use composite keys in tables that record which items are included in which shipments. A composite of shipment ID and item ID identifies each line of a shipment manifest, enabling accurate inventory reconciliation when goods arrive at a destination and need to be matched against expected contents.
Understanding these applications reinforces why composite key logic is not a theoretical database concept but a practical data integrity mechanism with measurable consequences when applied correctly or ignored. For analysts and data professionals who work with relational databases — designing schemas, writing queries, or validating data — fluency in composite key logic directly affects the reliability of the outputs they produce. This is why the concept features in the curriculum of any serious Data Analytics Course in Hyderabad, where learners work with realistic database scenarios that reflect the complexity of production data environments.
Composite Keys Versus Surrogate Keys: A Design Consideration
A recurring question in database design is whether to use a composite key as the primary identifier or to introduce a surrogate key — a single auto-generated column (typically an integer or UUID) that acts as a standalone identifier — while enforcing the composite uniqueness through a separate constraint.
Both approaches are valid, and the choice depends on context. Composite primary keys are self-documenting: the key itself communicates the business logic of what makes a record unique. They also avoid the overhead of an additional column. Surrogate keys, on the other hand, simplify foreign key relationships in dependent tables (a single column reference rather than multiple) and can improve join performance in certain query patterns.
In practice, many database architects use surrogate keys as primary keys for simplicity in large-scale systems while adding a UNIQUE constraint on the composite column combination to enforce data integrity at the business logic level. This hybrid approach captures the relational simplicity of a single-column primary key while retaining the uniqueness guarantee that the composite logic provides.
Evaluating these trade-offs requires a working knowledge of both relational database theory and the practical performance characteristics of the systems being designed. These design decisions are precisely the kind of applied reasoning developed through structured learning — a comprehensive Data Analytics Course in Hyderabad that covers relational modeling alongside SQL gives learners the conceptual grounding to make and justify these choices in professional settings, rather than simply implementing whatever pattern is most immediately familiar.
Conclusion
Composite keys address a specific and common problem in relational database design: situations where no single column is sufficient to uniquely identify a record, but a combination of columns is. By understanding the logic behind composite keys — when they are necessary, how they are implemented, how they affect queries and indexing, and how they relate to surrogate key alternatives — data professionals develop a more accurate model of how relational databases enforce integrity and structure information. This knowledge is not peripheral to analytical work; it is foundational to understanding the data that analysts query, join, and aggregate every day. As relational databases remain the dominant structure for operational and analytical data storage across industries, composite key logic continues to be one of the most practically relevant concepts in the data professional’s technical toolkit.
Name – ExcelR- Data Science, Data Analytics, Business Analytics Course Training Mumbai
Address – 304, 3rd Floor, Pratibha Building. Three Petrol pump, Lal Bahadur Shastri Rd, opposite Manas Tower, Pakhdi, Thane West, Thane, Maharashtra 400602
Phone No – 9108238354
Email Id – enquiry@excelr.com