Snowflake Schema Complexity: Normalizing Dimension Tables to Reduce Redundancy in Data Warehouses
Data warehouse design sits at the intersection of storage efficiency and query performance, and the schema chosen to organize that data has lasting consequences for both. The snowflake schema is one of the primary structural approaches used in data warehousing — an extension of the more familiar star schema that introduces additional layers of normalization into dimension tables. Understanding what snowflake schemas are, how they differ from simpler alternatives, and where their trade-offs matter most is essential knowledge for anyone working seriously with business intelligence systems or enterprise analytical environments.
From Star to Snowflake: Understanding the Structural Difference
To understand the snowflake schema, it helps to first understand what it extends. A star schema organizes a data warehouse into a central fact table — which contains measurable, numerical data like sales amounts, transaction counts, or patient visits — surrounded by dimension tables that describe the context of those measures. A dimension table might hold product information, customer demographics, store locations, or time attributes. In a star schema, each dimension table is flat and denormalized, meaning all descriptive attributes are stored in a single wide table regardless of whether some attributes belong to sub-groupings that repeat across many rows.
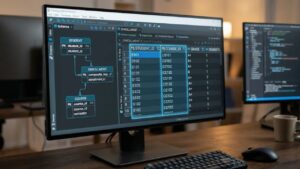
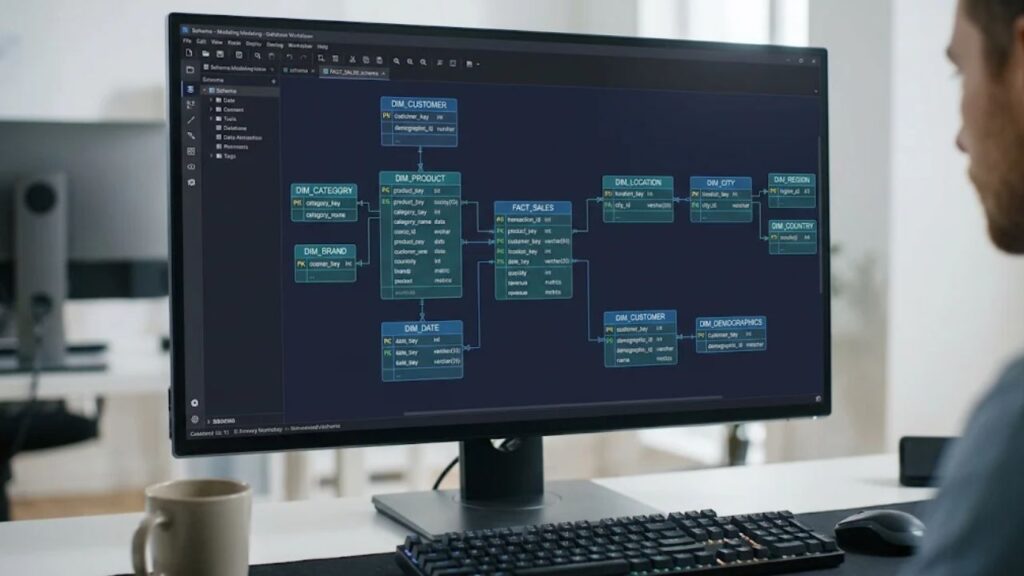
The snowflake schema takes those dimension tables and normalizes them — breaking them into multiple related tables to eliminate redundant data storage. The result, when diagrammed, looks like a snowflake rather than a simple star: the central fact table connects to dimension tables, which in turn connect to sub-dimension tables, creating a branching structure of related tables at multiple levels.
A concrete example illustrates the difference clearly. In a retail data warehouse using a star schema, a single product dimension table might contain columns for product name, product subcategory, product category, department name, and department manager — all in one flat table. If there are 10,000 products but only 5 departments, the department name and manager information is repeated across thousands of rows. In a snowflake schema, the product table contains only product-level attributes and a foreign key linking to a subcategory table. The subcategory table links to a category table, which links to a department table. Each piece of descriptive information exists in exactly one place, referenced by identifier rather than repeated by value.
This normalization is the defining characteristic of the snowflake schema, and it directly addresses data redundancy — a concern that becomes more significant as dimension tables grow larger and the repetition of high-level attribute values accumulates across millions of rows. The principles behind this design are foundational to dimensional modeling, a topic covered in depth in any serious Data Analytics Course that addresses data warehouse architecture.
Where Snowflake Schemas Add Value and Where They Create Complexity
The primary benefit of the snowflake schema is storage efficiency. By eliminating repeated values across dimension tables, it reduces the volume of data stored — particularly in dimensions with deep hierarchies where high-level attributes (department, region, product category) are shared across large numbers of lower-level records. In environments where storage costs are significant or where data governance requires that descriptive attributes be maintained in a single authoritative location, normalization is a meaningful advantage.
Maintenance and consistency represent a second benefit. In a flat star schema dimension table, updating a department manager’s name requires touching every row in the product table that belongs to that department — potentially thousands of records. In a snowflake schema, the same update touches exactly one row in the department table, and the change propagates automatically through the foreign key relationships. This reduces the risk of partial updates leaving the database in an inconsistent state, which matters in environments where dimension data changes regularly.
However, these benefits come with a trade-off that is central to the ongoing debate between snowflake and star schema adoption: query complexity and join performance. Because snowflake schemas distribute dimension data across multiple related tables, queries that need to access attributes from different levels of a dimension hierarchy must execute multiple joins to retrieve a complete picture. A query asking for sales by product category in a snowflake schema must join the fact table to the product table, the product table to the subcategory table, and the subcategory table to the category table — a chain of joins that a star schema resolves in a single join to one flat dimension table.
In modern columnar data warehouses like Snowflake, BigQuery, or Amazon Redshift, the performance impact of additional joins has diminished compared to older row-based systems, because these platforms optimize multi-table queries efficiently at scale. Nevertheless, in environments with very high query concurrency or strict response time requirements, the join overhead of a snowflake schema remains a legitimate performance consideration.
This trade-off — storage efficiency and maintenance simplicity on one side, query complexity and join overhead on the other — is precisely the kind of architectural decision that data engineers and BI architects must evaluate in context. Understanding how to reason through these trade-offs is a key component of a well-structured data analytics course in Mumbai, where learners work with real schema design scenarios that reflect the conditions encountered in production data warehouse environments.
Real-World Applications and Industry Context
Snowflake schemas appear across industries where data warehouses manage large volumes of descriptive dimensional data with meaningful internal hierarchies — conditions that make redundancy reduction worth the additional join complexity.
In retail and consumer goods, large supermarket chains and multi-brand retailers manage product hierarchies that can span five or more levels: individual SKU, product variant, product, subcategory, category, department, and division. Storing all of these attributes in a single flat product dimension table creates substantial redundancy when the warehouse contains millions of product-level transaction records. A snowflake schema’s normalized structure keeps each level of the hierarchy in its own table, making it easier to update category definitions or restructure the product hierarchy without triggering mass updates across the fact table’s dimension records.
In telecommunications, companies managing subscriber data across networks, service plans, regions, and device types use snowflake schemas to organize the complex hierarchical relationships between geographic areas (country, state, city, exchange, cell tower) and service infrastructure (network type, band, technology generation). The geographic dimension alone may have four or five levels of hierarchy, making normalization a practical necessity for maintaining referential integrity across large subscriber databases.
In financial services, investment management firms use snowflake schemas in their analytical data warehouses to organize instrument classifications — asset class, sector, industry, sub-industry, and individual security — in a normalized hierarchy. When regulatory reclassifications change how certain instruments are categorized at the sector or industry level, a normalized snowflake structure allows the update to be made once at the appropriate level rather than propagated across every row in the fact table that references affected securities.
In healthcare, hospital networks managing patient records across facilities, departments, specialties, and care teams benefit from snowflake-style organization of their provider and facility dimension hierarchies. A physician belongs to a specialty, which belongs to a department, which belongs to a facility, which belongs to a network. Normalizing these relationships ensures that administrative changes — a department reorganization or a facility merger — require updates in one place rather than across every patient encounter record.
Across these applications, the common thread is that snowflake schemas are most appropriate when dimension hierarchies are deep, when high-level attributes change periodically and need to be updated efficiently, and when the data warehouse platform is capable of handling multi-table joins at scale without significant performance degradation. Recognizing these conditions — and knowing when a simpler star schema is the more practical choice — requires the kind of applied architectural judgment that develops through structured, scenario-based training. A Data Analytics Course in Hyderabad that covers dimensional modeling alongside hands-on work in warehouse platforms gives learners the context to make these design decisions with confidence.
Snowflake Schema Versus Star Schema: Choosing the Right Design
The question of which schema to use is not settled by a universal rule but by the specific requirements of the analytical environment being designed. Several factors consistently inform the decision in practice.
When storage efficiency is a priority — either because of infrastructure cost constraints or because the dimension tables are very large with deep, repeating hierarchies — the snowflake schema’s normalization provides a measurable advantage. When query simplicity and response speed are the dominant concerns — particularly in self-service BI environments where non-technical users build their own reports — the star schema’s flat dimension structure reduces the join complexity that would otherwise burden every query.
Hybrid approaches are common in mature data warehouse environments. Organizations often use a star schema for their highest-traffic analytical queries while applying snowflake normalization to specific dimension hierarchies where the redundancy and maintenance burden of a flat table is genuinely problematic. This pragmatic middle ground reflects the reality that schema design is an applied discipline shaped by specific organizational needs rather than a theoretical preference for one pattern over another.
Developing the judgment to navigate these decisions is a core goal of dimensional modeling education. Any comprehensive Data Analytics Course that covers data warehouse design will address both the star and snowflake schemas — not as competing absolutes but as tools with different appropriate contexts, each grounded in the same foundational principles of separating facts from dimensions and organizing data to support efficient analytical queries.
Conclusion
The snowflake schema represents a deliberate architectural choice to prioritize storage efficiency and referential integrity over query simplicity in data warehouse design. By normalizing dimension tables into hierarchical sub-tables, it eliminates redundant storage of repeated attribute values and simplifies the maintenance of descriptive data that changes over time. Its trade-off — additional join complexity in analytical queries — is manageable on modern columnar warehouse platforms and acceptable in environments where the benefits of normalization outweigh the cost of more complex query structures. Across retail, telecommunications, financial services, and healthcare, the snowflake schema addresses real organizational needs that arise when dimensional hierarchies are deep and data governance requirements are rigorous. For data professionals, understanding both the structural logic and the practical trade-offs of the snowflake schema is a foundational component of warehouse design literacy — knowledge that informs better architectural decisions and more effective analytical system development.
Name – ExcelR- Data Science, Data Analytics, Business Analytics Course Training Mumbai
Address – 304, 3rd Floor, Pratibha Building. Three Petrol pump, Lal Bahadur Shastri Rd, opposite Manas Tower, Pakhdi, Thane West, Thane, Maharashtra 400602
Phone No – 9108238354
Email Id – enquiry@excelr.com