Supply Chain Delay Analysis: Using Time-Series Models to Identify Bottlenecks and Predict Lead Time Variance
Introduction
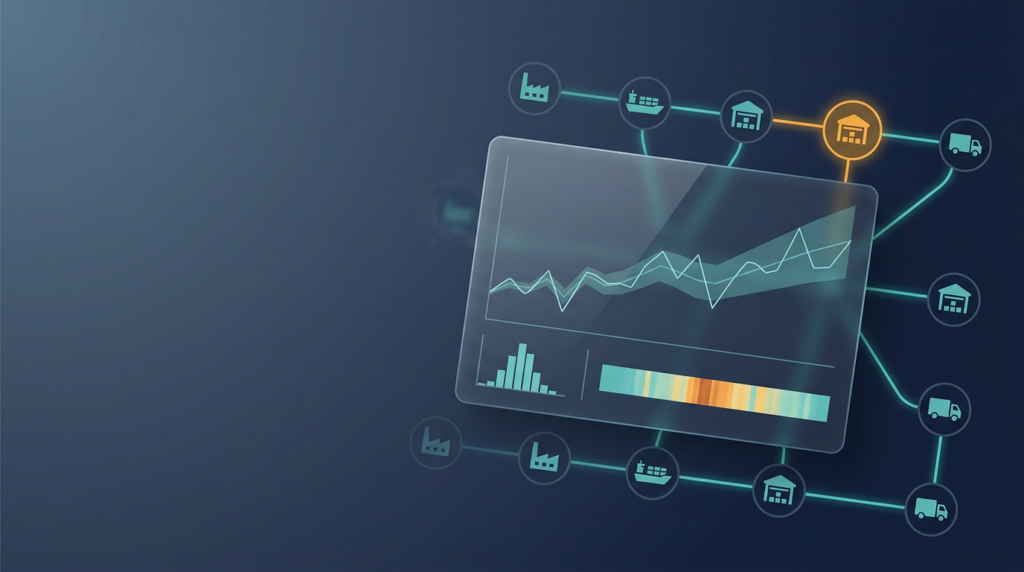
In a modern supply chain, a delay rarely comes from a single cause. A late shipment might be triggered by a production queue, a missed pickup slot, port congestion, documentation holds, or a supplier’s batch variability. The challenge for operations teams is not only to explain what happened, but also to predict what will happen next, with enough lead time to act. This is where time-series analysis becomes practical. By treating lead time as a measurable signal that changes over time, organisations can detect patterns, isolate bottlenecks, and forecast variance before it becomes customer impact.
For professionals learning analytics through a data analyst course in Pune, this topic is a useful bridge between statistical modelling and real operational decision-making. Likewise, anyone exploring a data analyst course will see how forecasting is not just a “data science” concept, but a daily requirement in logistics and planning.
Understanding lead time and delay signals
Lead time is typically defined as the duration between order release and delivery (or receipt). In reality, it is composed of smaller segments: supplier processing time, manufacturing cycle time, staging and dispatch, transit, customs (if applicable), and last-mile delivery. When delays occur, variance increases, meaning lead time becomes less predictable even if the average looks acceptable.
From a modelling perspective, you should track multiple time-series signals, not just a single end-to-end metric:
- Order-to-ship lead time (internal processing signal)
- Ship-to-deliver lead time (transport signal)
- Queue time at a node (warehouse, dock, or production queue)
- Exception counts per day (holds, damage, rework events)
- Capacity utilisation over time (labour hours, machine hours, carrier availability)
This decomposition matters because bottlenecks often hide inside averages. A plant might show “stable monthly lead time” but still experience sharp daily spikes when capacity crosses a threshold.
Data preparation: make the time-series trustworthy
Time-series models will only work if the underlying timestamps are consistent and comparable. A common pitfall in supply chain data is mixed definitions. Some teams store “dispatch date” as planned dispatch, others store it as actual dispatch. Another issue is missing event stamps, which creates artificial lead times.
A clean approach includes:
- Standardise event definitions: actual vs planned timestamps must be separate fields.
- Remove obvious data errors: negative lead times, duplicate events, or impossible sequences.
- Choose a stable frequency: daily aggregation often works better than per-order modelling when volumes are high.
- Adjust for seasonality: weekends, month-end closing, and holiday periods can distort the signal.
- Segment the series: separate suppliers, lanes, or product families, because one model rarely fits all.
If you skip these steps, the model may “predict” noise rather than operational behaviour.
Identifying bottlenecks with time-series diagnostics
Before forecasting, identify where delays originate. Time-series diagnostics help because they highlight changes in level, volatility, and recurring patterns.
Key methods include:
- Rolling averages and rolling variance: if variance rises sharply, the process is becoming unstable even if the mean is unchanged.
- Change-point detection: useful for spotting a sudden shift after a policy change, a new carrier, or a supplier transition.
- Autocorrelation patterns: if delays are correlated across days, the system may be experiencing backlog effects. For example, when yesterday’s overflow pushes into today’s workload, queues become self-reinforcing.
- Cross-correlation between nodes: when a spike at one warehouse consistently precedes a spike downstream, you have evidence of propagation rather than isolated disruption.
Practical example: if pick-pack queue time rises first, and transit delays rise two days later, the bottleneck is likely inside the dispatch process rather than transportation. That insight changes the action plan.
Forecasting lead time variance using time-series models
Forecasting the average lead time is useful, but forecasting variance is often more valuable because planners need confidence intervals, not just point estimates. A reliable forecast answers: “How wide will lead time uncertainty be next week?”
Common modelling options:
- Exponential smoothing (ETS): strong baseline model when trends and seasonality are present and interpretability matters.
- ARIMA/SARIMA: effective for structured time-series with autocorrelation and seasonal patterns.
- ARIMAX or dynamic regression: improves accuracy by adding external drivers such as fuel price indices, carrier capacity, order volume, weather disruptions, or port dwell time.
- State space models: useful when you want the model to adapt over time as process conditions change.
For variance specifically, teams often model not only lead time but also the absolute error or residual magnitude over time. If residuals grow during peak demand, you can forecast “risk of delay” as a time-series in itself.
The output should be operational: prediction intervals, not only predicted values. A procurement team can then choose safety stock levels based on expected volatility, and logistics can pre-book capacity when the forecast shows a risk spike.
Conclusion
Supply chain delay analysis becomes far more actionable when lead time is treated as a time-series signal rather than a static KPI. By cleaning event data, breaking lead time into segments, using diagnostics to find where instability begins, and forecasting both level and variance, organisations can reduce surprises and respond earlier. The most valuable outcome is not a perfect forecast, but a consistent early-warning system that highlights bottlenecks, quantifies uncertainty, and supports better planning decisions. For learners applying concepts from a data analysis course in Pune or strengthening practical analytics skills through a data analyst course, this is a highly relevant use case that connects modelling directly to cost, service levels, and customer trust.
Contact Us:
Name: Elevate Data Analytics
Address: Office no 403, 4th floor, B-block, East Court Phoenix Market City, opposite GIGA SPACE IT PARK, Clover Park, Viman Nagar, Pune, Maharashtra 411014
Phone No.: 095131 73277
Email: elevatedsda@gmail.com